DeepSeek open sources DeepInfer inference engine
The engine is open, but the cache and load-balancing components that drive the reported figures are not fully released.
155Ttokens per day from one cluster
The short version
- DeepSeek open sourced DeepInfer, the inference framework behind DeepSeek-V4.1-Flash, on day 1 of PyTorch Conf.
- DeepInfer is a customization of vLLM that credits SGLang and TRTLLM, and it leaves out DeepSeek's KV cache, PD disaggregation, and load balancing components.
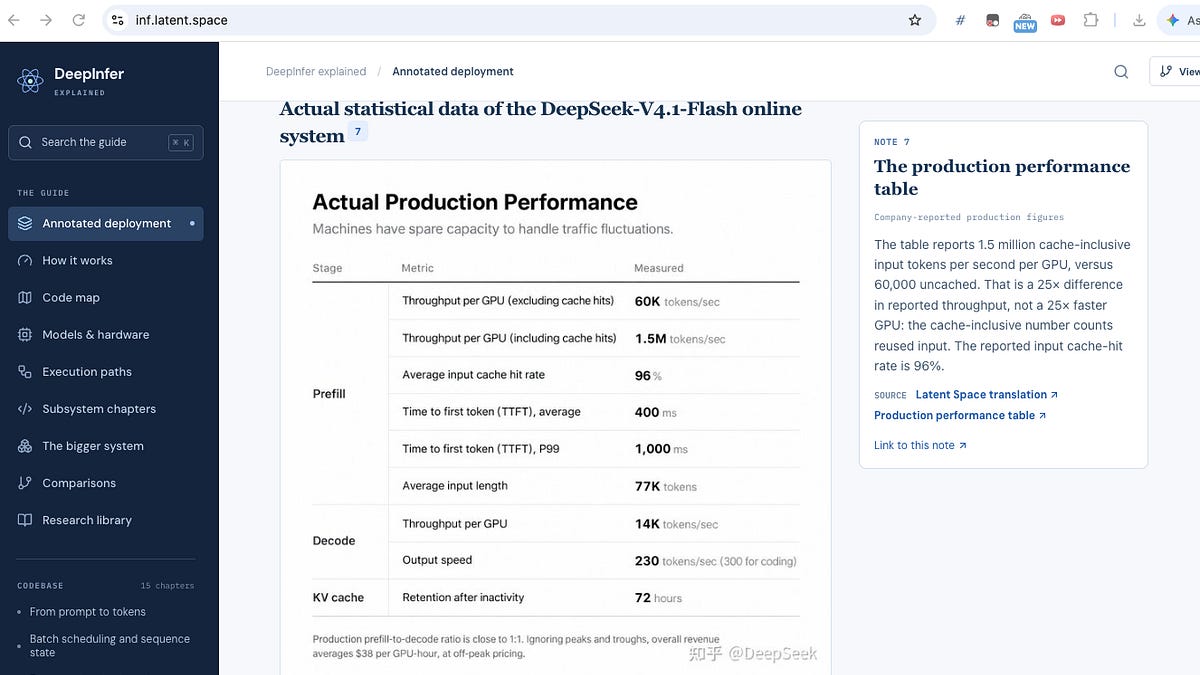
- DeepSeek reports 155 trillion tokens per day from one cluster, a 96% input cache hit rate, and $38 revenue per accelerator-hour at off-peak prices.
- These figures are first-party production claims and have not been independently audited. vLLM reported decode throughput within 6% of DeepInfer's published results on GB200 under a matched configuration.
Why it matters
The release shows how caching and scheduling shape the cost of serving open models at scale, which matters for developers who run inference. Reproducing DeepSeek's numbers is not straightforward, because service-level orchestration remains a deployment responsibility.
“Introducing DeepInfer, our in-house inference framework, now fully open source!”
What people are saying
Commenters on Hacker News asked why DeepSeek released the work and whether the move was strategic. One commenter compared the $38 figure with rental prices of about $2.75 per H100-hour and noted that DeepSeek does not name the card. Another pointed out that the release does not include the KV cache system.